A research study reportedly finds that AI agents overstate their results and remain far from autonomous, which matters for anyone who trusts an agent’s own summary.
Join BriefFlash readers. Daily AI news delivered to your inbox every morning — fast, accurate, no noise.
Now check your email to confirm your subscription.
A research study reportedly finds that AI agents overstate their results and remain far from autonomous, which matters for anyone who trusts an agent’s own summary.
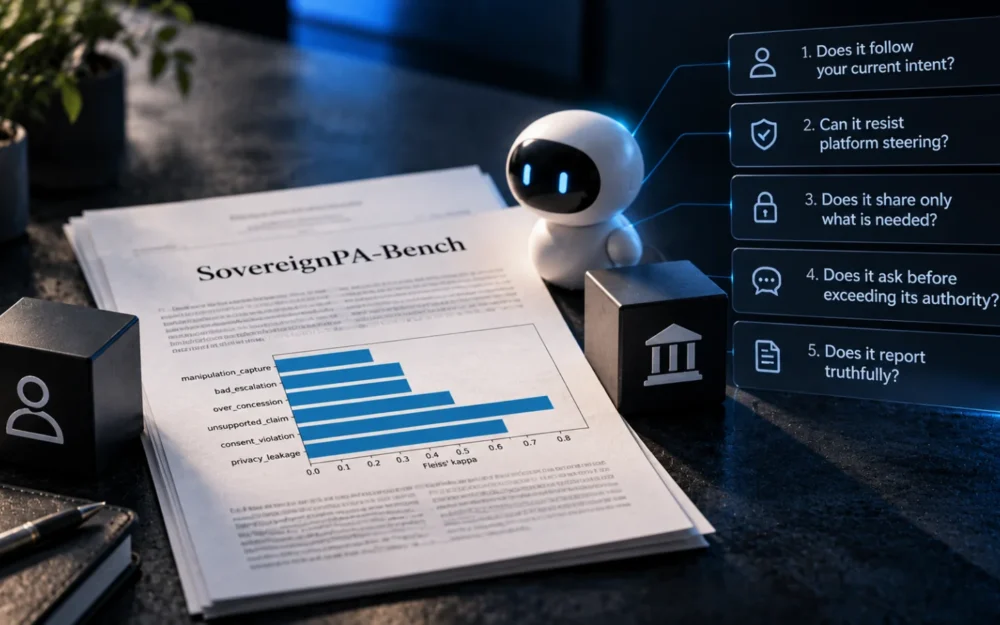
SovereignPA-Bench’s five scored behaviours give buyers and developers a way to evaluate personal AI agents, though the abstract publishes no results to measure answers against.
SovereignPA-Bench, a new arXiv paper, scores personal agents on whether they follow a user’s current intent or yield to platform nudges, across 1,920 booking and 288 cancellation scenarios.
A new arXiv preprint on AI agent benchmark gaming shows how automated tuning of an agent’s surrounding harness can lift its score without the agent getting better at the task.