AI Research covers the latest breakthroughs in artificial intelligence, machine learning, deep learning, and generative AI. Discover new research papers, benchmark results, academic studies, and innovations from leading universities, research labs, and technology companies.
BriefFlash reports on advances in large language models, computer vision, robotics, reinforcement learning, multimodal AI, and scientific discoveries. Stay informed with expert analysis of the latest developments shaping the future of artificial intelligence.
A post argues that open benchmarks for frontier AI need to keep up as models accelerate. What benchmarks do, why they age, and what the argument leaves open.
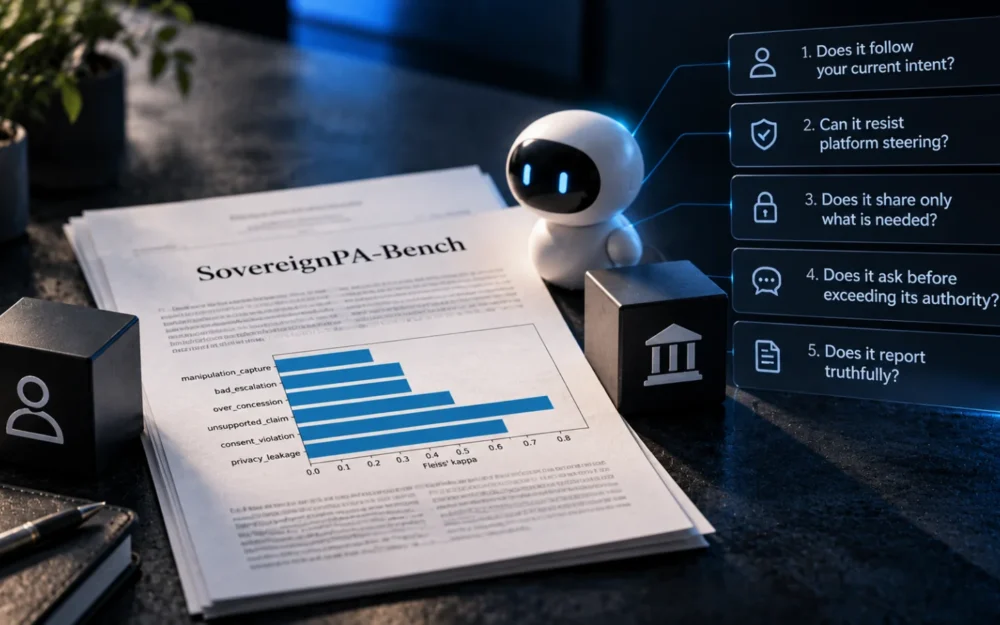
SovereignPA-Bench’s five scored behaviours give buyers and developers a way to evaluate personal AI agents, though the abstract publishes no results to measure answers against.
SovereignPA-Bench, a new arXiv paper, scores personal agents on whether they follow a user’s current intent or yield to platform nudges, across 1,920 booking and 288 cancellation scenarios.
Drunk language LLM safety research induced drunk-style writing in 5 models three ways and reports higher jailbreak susceptibility; the abstract does not size the effect.
Scientific agents system prompts built from 503 profession-specific profiles raised token use and estimated cost, the paper reports, without a consistent accuracy gain.
A new preprint asks how domain adaptation affects small language models trustworthiness in healthcare, legal and finance work, but the available text shows no results.
A new arXiv preprint on frontier learning LLM reasoners argues that fixed problem sets go stale under GRPO training. Here is the claim, and what remains unproven.