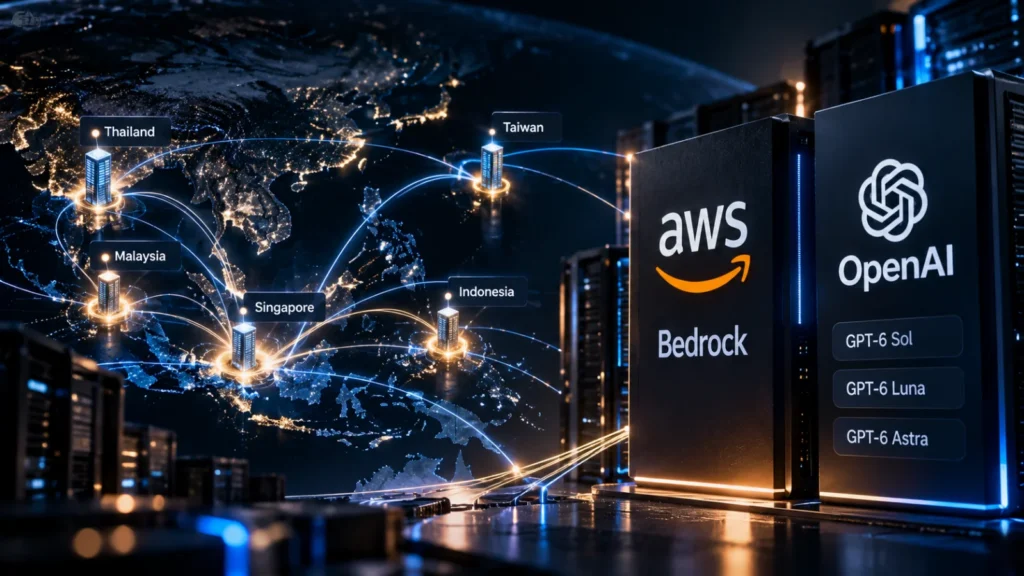
AWS says Amazon Bedrock offers OpenAI GPT-6 Sol and GPT-6 Luna through global cross-Region inference from all five of its AWS Regions in Thailand, Malaysia, Singapore, Indonesia and Taiwan. GPT-6 Astra, the third model AWS names, is available from Asia Pacific (Singapore), according to the same post.
For teams weighing OpenAI GPT-6 on Amazon Bedrock, the reason AWS gives is capacity: it says single-Region inference can throttle when demand exceeds what a Region can serve locally. The change matters most to production teams in those five places, but the material BriefFlash has leaves open where requests are actually processed and what the service costs.
Which models does OpenAI GPT-6 on Amazon Bedrock offer in each Region?
AWS names three models, and the routes differ. Sol and Luna are offered through global cross-Region inference from all five Regions, while Astra is available from Asia Pacific (Singapore). The table sets out that picture as AWS describes it.
| Model | Asia Pacific Regions named by AWS | Access route stated by AWS |
|---|---|---|
| GPT-6 Sol | Thailand, Malaysia, Singapore, Indonesia, Taiwan | Global cross-Region inference |
| GPT-6 Luna | Thailand, Malaysia, Singapore, Indonesia, Taiwan | Global cross-Region inference |
| GPT-6 Astra | Asia Pacific (Singapore) | Available from Singapore; routing method not stated |
Two details need care. The Astra line says where the model is available, not that it can be reached through global cross-Region inference, and BriefFlash does not read it as the latter. BriefFlash has also worked from AWS’s summary of the post rather than its full text, so we do not infer further models or Regions beyond the three AWS names.
What is global cross-Region inference, and why does throttling push teams toward it?
Global cross-Region inference lets a request run on capacity in other Regions when the local Region is saturated, and “global” means the routing is not confined to one geography. Amazon Bedrock is AWS’s managed service for reaching foundation models through one API, so the idea is that teams keep one integration point while capacity comes from wherever it is available.
Throttling is the failure this addresses. AWS says single-Region inference can throttle when demand exceeds local capacity. In a production application that shows up as failed or delayed calls under load, which users experience as errors or lag. A prototype can absorb that; a customer-facing feature usually cannot.
The source Region is where the application sends the call. AWS says its post shows how to configure the call, set permissions and monitor inference from that Region. BriefFlash is not repeating configuration steps, because the material we have does not include them.
Who is affected, and what should teams check first?
Teams building on AWS in Thailand, Malaysia, Singapore, Indonesia and Taiwan are the group AWS addresses. It frames their need as access to the newest OpenAI models beyond local capacity, which we read as a sign that local capacity alone was not enough for some workloads. AWS gives no figures on how often throttling occurred.
Before routing production traffic, platform engineers can work through four checks:
- Confirm where requests are processed under global cross-Region inference before sending regulated data.
- Check Bedrock pricing for the exact model and routing option, since the material we have gives no figures.
- Test latency from your source Region under realistic load.
- Find out whether Astra can use cross-Region inference or is reachable only from Singapore.
This is AWS offering models on its own platform. It is not OpenAI launching or expanding operations in these countries, and nothing in the material suggests otherwise.
Is GPT-6 Sol on Bedrock the same as GPT-6.1 Sol?
The material available to BriefFlash does not say. AWS names GPT-6 Sol, while BriefFlash earlier covered GPT-6.1 Sol and its pricing against Astra, where OpenAI says GPT-6.1 Sol launches at a fifth of Astra’s price. Those are different version labels, and nothing here says the newer one is on Bedrock, so availability should not be assumed.
For wider context, BriefFlash has covered how OpenAI and AWS launched Daybreak Red & Blue on Bedrock, and has reported, citing OpenAI, that Perplexity trusts GPT-6 Astra with its production systems. Neither changes what AWS has or has not said about these Regions.
What has AWS not said about data residency, price and latency?
In the material BriefFlash has, AWS does not say where requests are processed under global cross-Region inference. Because global routing is not limited to one geography, better capacity access does not remove the need to confirm where data is handled, and we are not assuming it stays in the source Region. For teams with residency or compliance obligations, that is the first question to settle.
Pricing is also absent, including any difference from direct access through OpenAI. So are latency effects of routing across Regions, quotas and throttling limits, and whether Astra is reachable through cross-Region inference or only from Singapore.
Everything above is AWS describing its own service. There is no independent test of reliability or latency in the material, so the capacity benefit is AWS’s claim until teams measure it themselves.
What would settle the open questions
The material gives no dates for further rollout, so there is no calendar item to track yet. The most useful follow-ups would be AWS documentation on where cross-Region requests run, published pricing for Sol, Luna and Astra on Bedrock, and independent latency tests from Asia Pacific source Regions. Until those appear, BriefFlash treats availability as AWS’s statement.
Frequently asked questions
What is global cross-Region inference on Amazon Bedrock?
Global cross-Region inference is a way for Amazon Bedrock to send a request to capacity in other AWS Regions when the Region the application calls from is saturated. The word global means the routing is not limited to one geography. AWS says it addresses throttling, which can occur with single-Region inference when local demand exceeds capacity.
Which GPT-6 models are available on Amazon Bedrock in Asia Pacific?
AWS names three: GPT-6 Sol and GPT-6 Luna, offered through global cross-Region inference from all five Asia Pacific Regions (Thailand, Malaysia, Singapore, Indonesia and Taiwan), and GPT-6 Astra, which AWS says is available from Asia Pacific (Singapore). BriefFlash has worked from AWS’s summary of the post and does not infer further models or Regions.
Does global cross-Region inference affect data residency?
The material available to BriefFlash does not say where requests are processed under global cross-Region inference. Because global routing is not limited to one geography, teams with residency or compliance obligations should not assume data stays in the source Region. They should confirm processing locations in AWS documentation before sending regulated data through this route.
Does using GPT-6 models through cross-Region inference cost more?
Pricing for these models on Amazon Bedrock, and any difference from direct access through OpenAI, is not given in the material available to BriefFlash. Treat cost as unknown until you confirm figures from AWS for the specific model and routing option. Teams should also check quotas, which are likewise unstated, before planning production volume.