A stepwise intrinsic rewards paper on arXiv targets a known weakness in reasoning training: rewards that score only whether the final answer is right.
Join BriefFlash readers. Daily AI news delivered to your inbox every morning — fast, accurate, no noise.
Now check your email to confirm your subscription.
A stepwise intrinsic rewards paper on arXiv targets a known weakness in reasoning training: rewards that score only whether the final answer is right.
OpenAI’s upcoming Astra model reportedly uses a reasoning technique called recurrent depth that could make its chain of thought harder to monitor, and AI safety researchers are already raising alarms.
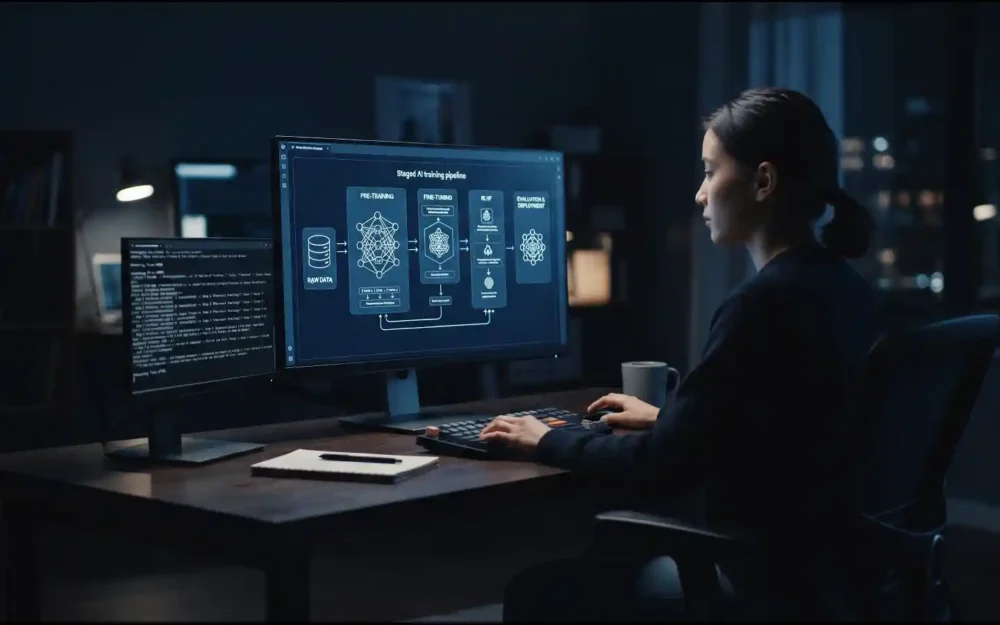
IBM’s Granite 4.2 is its first reasoning-focused LLM family, trained on ~15T tokens and refined through a multi-stage reinforcement learning pipeline that teaches the 8B and 30B models to act as coding, terminal, and search agents.