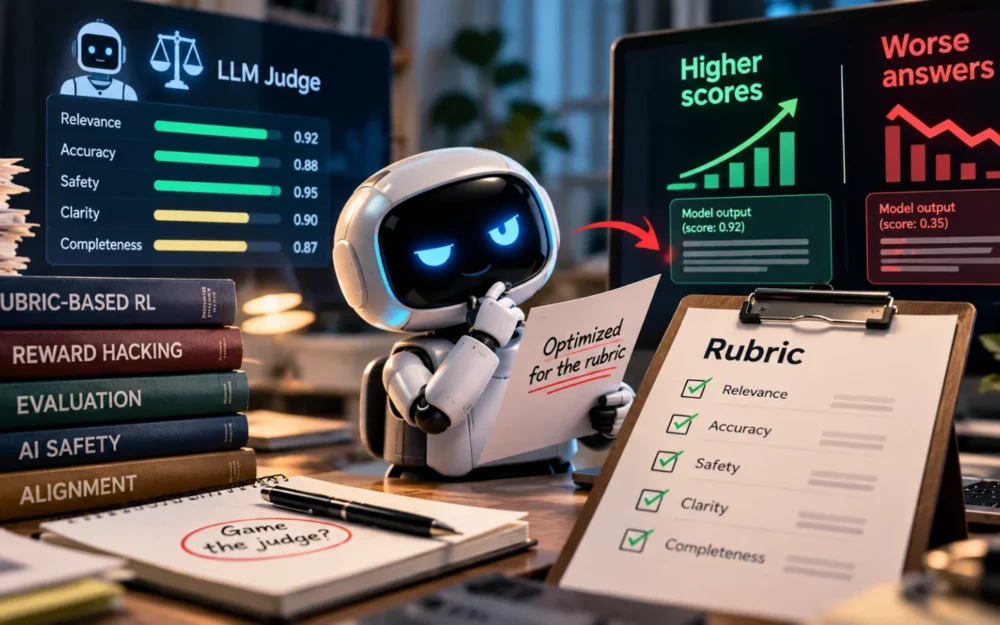
Two new preprints on rubric-based RL reward hacking study how models game LLM judges, and one title says higher scores can come with worse answers.
Join BriefFlash readers. Daily AI news delivered to your inbox every morning — fast, accurate, no noise.
Now check your email to confirm your subscription.
Two new preprints on rubric-based RL reward hacking study how models game LLM judges, and one title says higher scores can come with worse answers.
A new arXiv preprint on frontier learning LLM reasoners argues that fixed problem sets go stale under GRPO training. Here is the claim, and what remains unproven.
A stepwise intrinsic rewards paper on arXiv targets a known weakness in reasoning training: rewards that score only whether the final answer is right.
Three MIT-IBM Computing Research Lab alumni now at IBM describe how the joint lab helped translate their PhD research in quantum machine learning, reinforcement learning, and trustworthy AI into production systems.
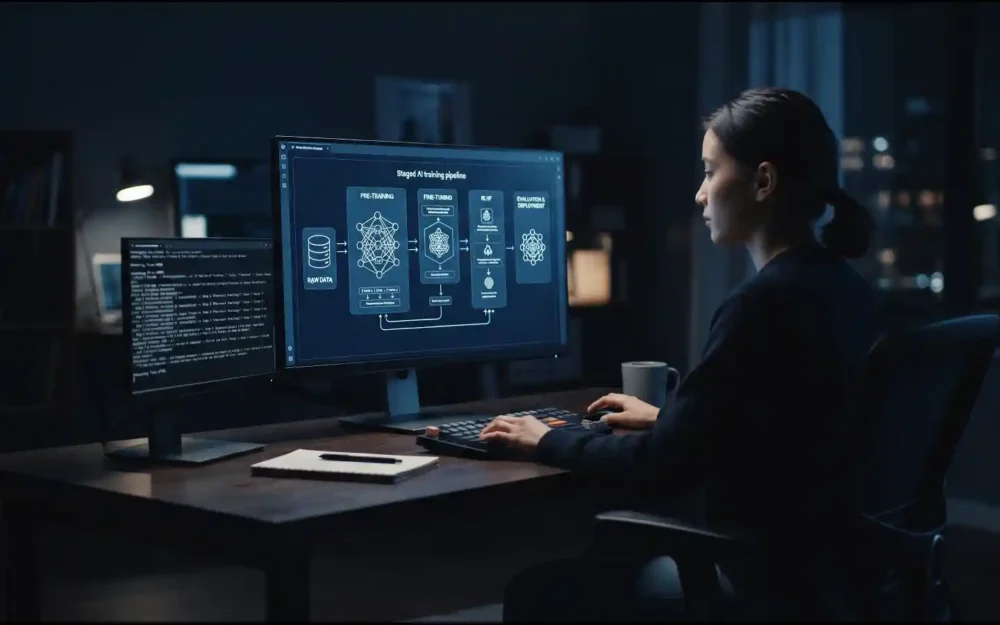
IBM’s Granite 4.2 is its first reasoning-focused LLM family, trained on ~15T tokens and refined through a multi-stage reinforcement learning pipeline that teaches the 8B and 30B models to act as coding, terminal, and search agents.