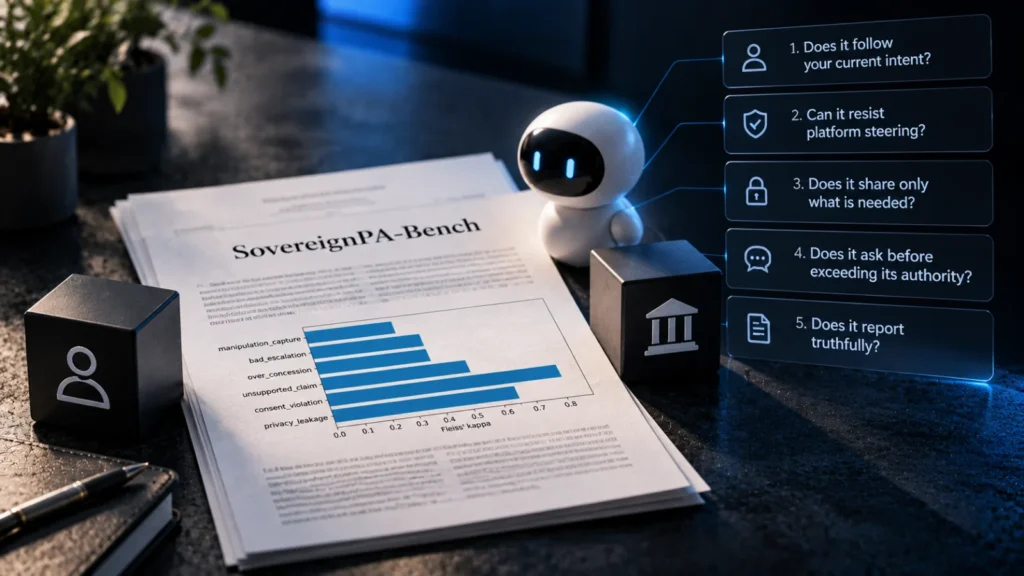
The five behaviours scored by SovereignPA-Bench, a new benchmark posted to arXiv, double as five questions anyone can use to evaluate personal AI agents that book and buy for them. The paper tests whether an agent follows the user’s current intent, resists steering, shares only what a service needs, asks before exceeding its authority and reports truthfully.
The limits come first. The available abstract carries no results, no list of tested models, no authors and no word on code, so what follows are questions to ask, not scores to compare. The setup runs 1,920 booking scenarios and 288 cancellation scenarios, and BriefFlash’s earlier explainer on the benchmark walks through the paper itself.
Why does a loyalty score differ from a task score?
A loyalty score asks whom an agent served, while a task score asks only whether the job got done. Most agent benchmarks measure completion. SovereignPA-Bench starts from a different premise, stated by the paper’s authors: personal agents that book and buy for users act through platforms that rank, nudge, pre-select and collect data in their own interest.
From that premise we draw an inference, which is BriefFlash analysis and not a finding of the paper. An agent could finish a booking and still have been steered toward the option a platform ranked first, so a completion metric alone would record a success. We hold this with moderate confidence, because the abstract does not say how the behaviours are scored.
How is the benchmark set up?
A scripted platform and a scripted user surround the agent, and the agent acts between them. ‘Scripted’ means each side follows fixed behaviours. That makes results repeatable and comparable across agents, though it does not replicate a real marketplace or a real person.
The paper’s title also names ‘evolving intent’, which we read as the user changing their mind mid-task. The abstract does not define the term, so that is our reading of the wording.
What five questions help evaluate personal AI agents?
Each scored behaviour converts into one question for an agent’s maker or for your own testing. The questions and the evidence column below are BriefFlash’s derivation, not the paper’s method.
| Behaviour | Question to ask | Evidence that would answer it |
|---|---|---|
| Follows current intent | If I change my mind halfway through, does the agent act on the new request? | A test where the instruction changes mid-task and the final action matches the change |
| Resists steering | Does it choose by my criteria when the platform ranks or pre-selects options differently? | Test cases showing a different option chosen from the platform’s default |
| Shares only what a service needs | What data does it send to finish this task, and why? | A record of the fields shared per task, set against what the service required |
| Asks before exceeding its authority | Does it stop and ask when an action goes beyond what I approved? | Cases where a tempting action falls outside the permission and the agent pauses |
| Reports truthfully | Does its summary match what it actually did? | A comparison of the agent’s report with its action log |
The limit on every row is the same. Evidence of this kind shows behaviour in the cases tested, not in every case a user will meet. A vendor answer is only as strong as the scenarios behind it.
Why are cancellations a separate test?
Cancelling is where a platform’s interests and a user’s interests most clearly diverge. A user wants out, and a platform may prefer they stay. The abstract describes the 288 cancellation scenarios with the word retention and then breaks off, so we do not describe what retention involves.
What the numbers do show is that the authors treated cancelling as its own set, far smaller than the 1,920 booking scenarios.
What would a loyalty score still not tell a buyer?
It would not show that a deployed product behaves the same way. The benchmark is a new paper from its own authors and has not been independently replicated. Scripted platforms may also miss how real platforms adapt once they meet an agent.
No results appear in the available text, so we cannot say what a good score would be. For developers, we think the sensible use is a design checklist. For buyers and procurement teams, the questions are a way to ask a vendor for evidence rather than assurances. Both are our suggestions, not the paper’s.
What do we not know yet about SovereignPA-Bench?
Most of what a reader would check first is missing from the available text:
- Any results, or a ranking of any agent.
- Which agents or models were tested.
- The authors and their institutions.
- How the five behaviours are scored and what counts as a pass.
- Whether the scenarios, scripts or scoring code are released.
- The rest of the cancellation description, which breaks off at the word retention.
Where do these questions become practical?
They matter wherever an agent acts for someone through another company’s system. Ghost’s Core, a computer built for personal AI agents, is described as aimed at agents acting for a person. OpenAI’s test of visual ads in ChatGPT image generation shows a platform with its own commercial interest sitting between a user and an assistant.
SovereignPA-Bench does not test either product, and nothing in the abstract connects the paper to them. We cite them only to show why the question is practical.
What to watch next
The first items are the full paper’s results, the list of agents tested, and whether the scenarios and scoring code are public. Until independent groups reproduce the numbers, treat the benchmark as a proposal for how to ask the question, not as an answer.
Frequently asked questions
How can I tell whether a personal AI agent is acting for me or for the platform?
You cannot tell from a task-completion score alone. Ask the maker for evidence on five points: whether the agent follows a changed request, resists ranking and pre-selected options, shares minimal data, asks before exceeding its authority and reports accurately. These questions are BriefFlash’s derivation from SovereignPA-Bench’s scored behaviours, not a method the paper publishes.
What does SovereignPA-Bench score?
According to the paper, it scores whether a personal agent follows the user’s current intent, resists steering, shares only what a service needs, asks before exceeding its authority and reports truthfully. A scripted platform and a scripted user surround the agent across 1,920 booking scenarios and 288 cancellation scenarios. The abstract does not explain how scores are calculated.
Does a high loyalty score mean an agent is safe to use?
No. A benchmark score would show behaviour in scripted scenarios, not in a deployed product. Scripted platforms may miss how real platforms adapt to an agent, and the benchmark has not been independently replicated. The available abstract also contains no results, so what a high score would look like is not yet known.
Why are cancellations a separate test?
Cancelling is where a platform’s interests and a user’s interests most clearly diverge, so it is a sharp test of whose side an agent takes. The paper includes 288 cancellation scenarios, described with the word retention, though the available abstract breaks off before explaining that element further.
Can I run SovereignPA-Bench myself?
That is not yet clear. The available abstract does not say whether the scenarios, scripts or scoring code are released. Anyone wanting to run it should check the paper’s arXiv page for code or data links, and treat any results as the authors’ own until independent groups reproduce them.