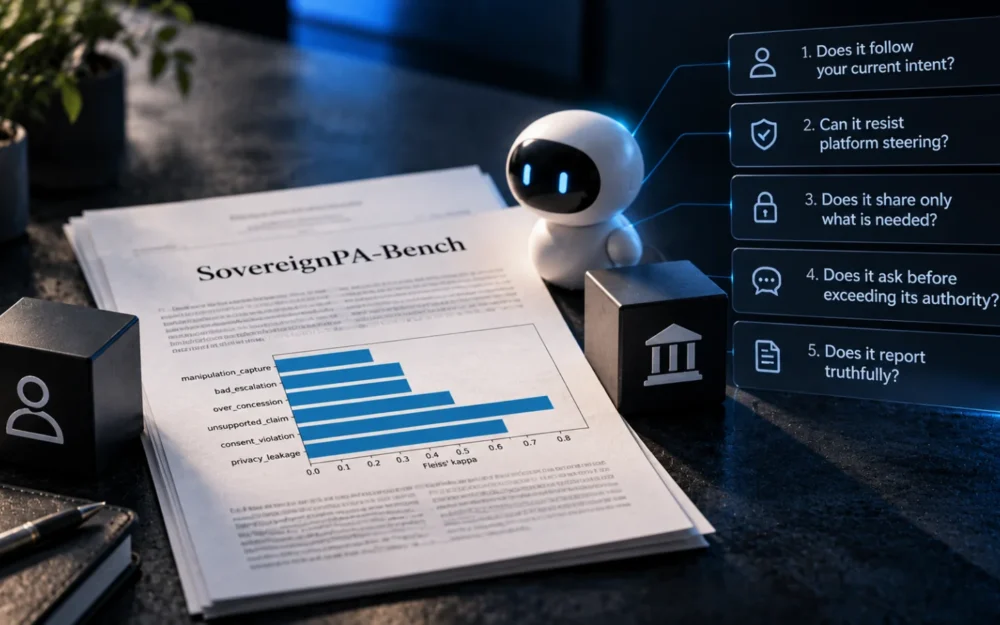
SovereignPA-Bench’s five scored behaviours give buyers and developers a way to evaluate personal AI agents, though the abstract publishes no results to measure answers against.
SovereignPA-Bench, a new arXiv paper, scores personal agents on whether they follow a user’s current intent or yield to platform nudges, across 1,920 booking and 288 cancellation scenarios.
A new arXiv preprint on frontier learning LLM reasoners argues that fixed problem sets go stale under GRPO training. Here is the claim, and what remains unproven.
A new arXiv preprint on AI agent benchmark gaming shows how automated tuning of an agent’s surrounding harness can lift its score without the agent getting better at the task.
A new preprint argues that repeated rows in benchmark tables quietly inflate anomaly detection scores, and audits all 690 OddBench datasets to check how often it happens.
The Agent-Editing World Model preprint says predicting tool outputs adds little when real feedback exists, and names task-state contamination as a separate problem.
Alex Carter•
BriefFlash Dispatch
The intelligence you need, delivered daily.
Get the biggest AI stories delivered to your inbox. Unsubscribe anytime.
Expert analysis
Exclusive interviews
Market intelligence
Success!
Now check your email to confirm your subscription.