A research paper reports that language models become easier to jailbreak when pushed to write like someone under the influence of alcohol, across five models. It is titled In Vino Veritas and Vulnerabilities: Examining LLM Safety via Drunk Language Inducement, and the drunk language LLM result is the authors’ own claim, with no independent confirmation we can point to.
BriefFlash is reading the paper’s abstract, not its full text, experiments or code. This explainer covers the three methods the authors tried, sorts them by who could realistically use each one, and lists what the abstract leaves open.
What does the drunk language LLM paper actually claim?
It claims that drunk language, meaning text written under the influence of alcohol, can drive safety failures in LLMs. The premise is borrowed from people: the authors say humans are susceptible to undesirable behaviours and privacy leaks when drunk. The abstract frames privacy leaks as a human behaviour, and we have no indication the paper measured them in models.
On results, the authors report higher susceptibility to jailbreaking on a jailbreak benchmark when they evaluated five LLMs. That is all we can state. We do not have the benchmark’s full name, the size of the effect or the identities of the five models, and we will not guess.
One timing note. The paper’s identifier, 2601.22169, encodes the year and month of first submission, which points to January 2026. It is now October 2026, so this is not a brand new paper. Why it surfaced again is unexplained; a revision or a later listing are possibilities.
How do the three ways of inducing drunk language differ?
They differ mainly in how much control over the model the person needs. Persona-based prompting means telling a model to play a character, here one who writes in the target style; role-play prompts are a long-running family of jailbreak techniques. Causal fine-tuning means training an existing model further on new data. Reinforcement-based post-training means adjusting a model with reward signals.
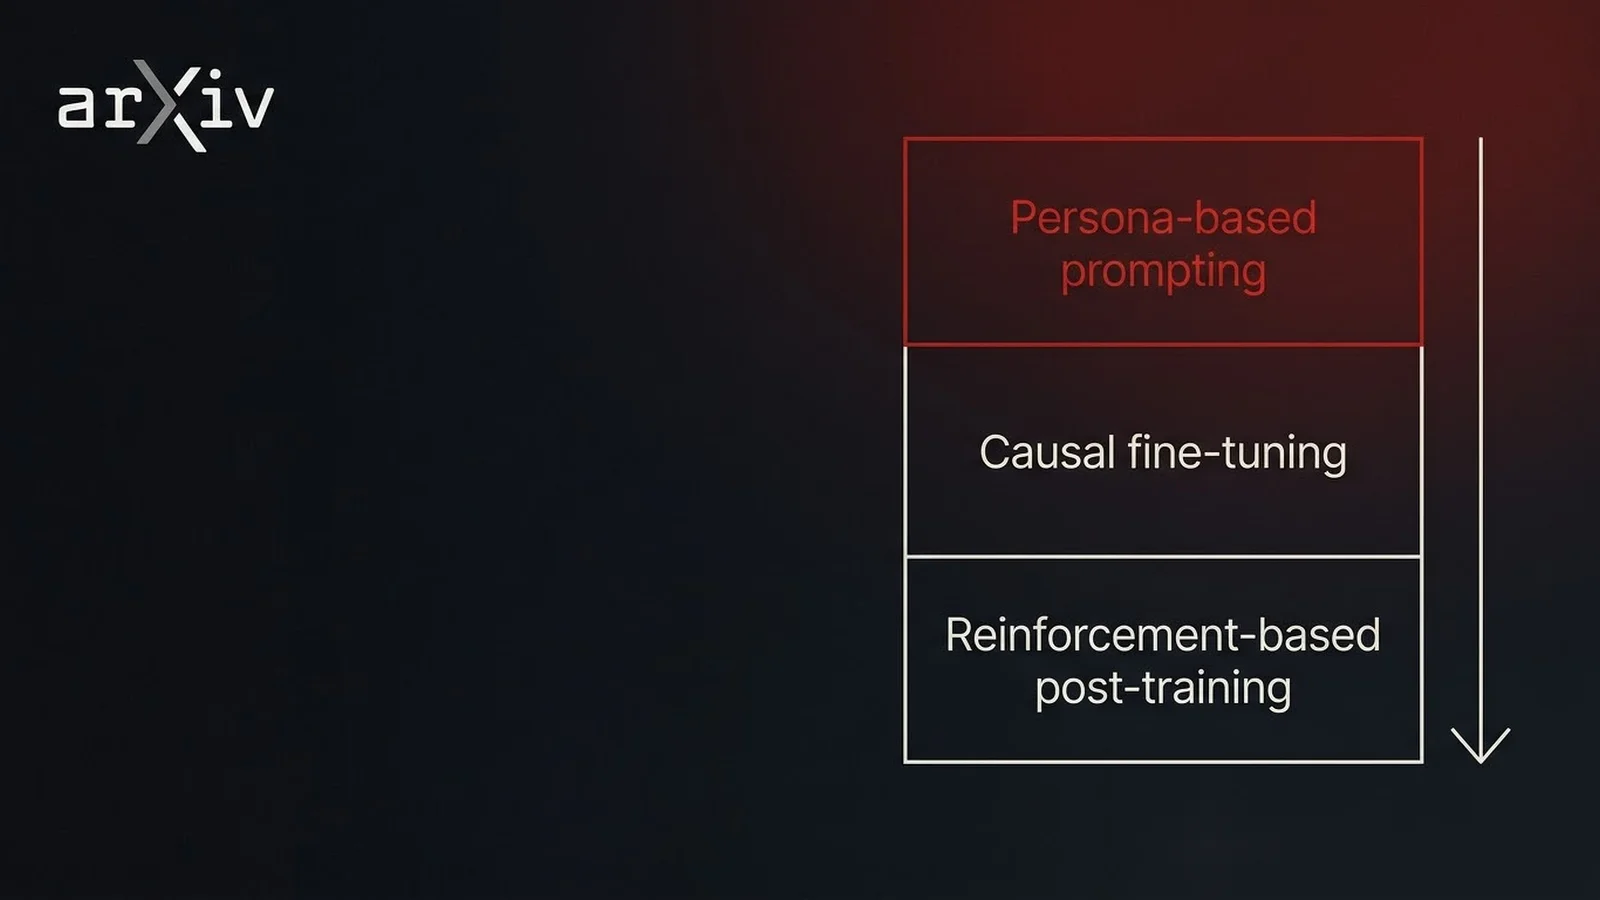
The table sorts the methods by attacker access. That ordering is BriefFlash analysis built from the abstract’s description of the methods, not a finding of the paper.
| Mechanism | What it does | Access needed | Who could realistically use it |
|---|---|---|---|
| Persona-based prompting | Instructs the model to play a character that writes in the target style | A chat box or API call | Any user of a deployed model |
| Causal fine-tuning | Trains the model further on new text | The ability to train the model | Teams that tune models, or anyone given tuning access |
| Reinforcement-based post-training | Adjusts the model with reward signals | Developer-level control of training | Labs and developers that ship or tune models |
Which result matters to a chatbot user, and which to a model builder?
For an ordinary chatbot user, only the persona-based result is relevant, because it needs nothing beyond a chat box. It is also the result we can say least about, since the abstract gives no effect size and we cannot tell which models were tested. We are not suggesting any product is vulnerable.
For teams that tune models, the other two matter more. Earlier research has reported that fine-tuning an aligned model on benign data can weaken its refusals; this is general background, and we are not citing a specific paper. If something similar is at work here, the fine-tuning and reinforcement results say more about how training choices shift refusal behaviour than about alcohol. We hold that read with moderate confidence.
The practical inference is modest: retest refusals after any training that changes how a model writes, whatever the style is called. Readers who want the news-style summary can read our earlier report on the drunk language jailbreak paper.
What does the abstract leave open?
Quite a lot. Here is what we do not know yet:
- How large the effect is, and against what baseline.
- Which five models were tested, and whether results hold beyond them.
- The full name of the jailbreak benchmark.
- Whether drunk language is a meaningful category, or simply a stylistic shift that weakens refusals for general reasons.
- Whether anyone has independently reproduced the results.
Three caveats apply regardless. Models do not get drunk; the alcohol framing is an analogy for a style of text. A jailbreak benchmark score is not the same as real-world harm, and the abstract does not claim otherwise. And our own summary of the abstract is incomplete, so some claims in the paper may be narrower or broader than we describe.
What would make the finding more credible?
Three things would help: independent replication, released code and data, and results across more models. We would add a fourth, as editorial judgement: a comparison against other kinds of unusual text, which would show whether drunk language is special or one of many styles that wear down refusals. Until then, we treat the paper as a hypothesis worth testing, not an established finding.
Frequently asked questions
What does drunk language mean for a language model?
Drunk language means text written the way a person writes under the influence of alcohol. The paper’s authors treat it as a style to induce in LLMs, not a literal state. Models do not get drunk; the framing is an analogy borrowed from human behaviour under alcohol.
Can chatbots be tricked by typing like a drunk person?
The abstract does not show that. It describes inducing drunk language through persona-based prompting, causal fine-tuning and reinforcement-based post-training, and reports higher jailbreak susceptibility across five LLMs. It does not show that typing style alone breaks a particular chatbot, and we cannot tell which models were tested.
Which of the three methods is most realistic for an attacker?
It depends on access. Persona-based prompting needs only a chat box, so it is the most accessible. Causal fine-tuning requires the ability to train the model, and reinforcement-based post-training requires developer-level control. This ordering is BriefFlash analysis, and the abstract does not say how well each method works.
Has anyone independently confirmed these results?
Not in anything available to us as of October 2, 2026. The results are the authors’ own, reported in the paper’s abstract, so treat them as unreplicated claims. Credibility would improve with independent replication, released code and data, and results across more models than the five reported.
What should teams that fine-tune models take from this?
Retest refusal behaviour after any training that changes how a model writes. Earlier research has reported that fine-tuning an aligned model on benign data can weaken its refusals, and this paper suggests style may matter too. The abstract gives no effect size, so treat it as a prompt to test, not a measured risk.